Import Data from Databricks to Netcore
Import Databricks contact data to power targeted campaigns and journeys in Netcore CE.
Overview
The Databricks contact import moves contact data from a Databricks table or view into Netcore CE. You choose the Databricks connection, catalog, schema, and table. You map the table columns to Netcore CE attributes. You then run the import once or on a recurring schedule.
Databricks Contact Import at a Glance
| Item | Detail |
|---|---|
| Source | Databricks |
| Destination | Netcore CE contact master, and optionally one or more lists |
| Location in Netcore CE | Settings > Data transfer > Import |
| Import type covered in this guide | Contacts |
| Wizard steps | Setup, Data mapping, Schedule |
| Required identity mapping | EMAIL (Primary key) and Updated on |
| Schedule options | One-time or Recurring |
| Recurring behavior | The first run transfers the complete dataset. Later runs transfer incremental data. |
Pre-requisites
- You must have an active Databricks connection of type Import in Netcore CE. See Databricks.
- You must have read access to the Databricks catalog, schema, and table or view you want to import from.
- Decide in advance which Netcore CE list, if any, you want to add imported contacts to.
- Decide which email addresses receive import alerts. Alert email is a required field.
Start a Databricks Data Import
Follow these steps to start an import.
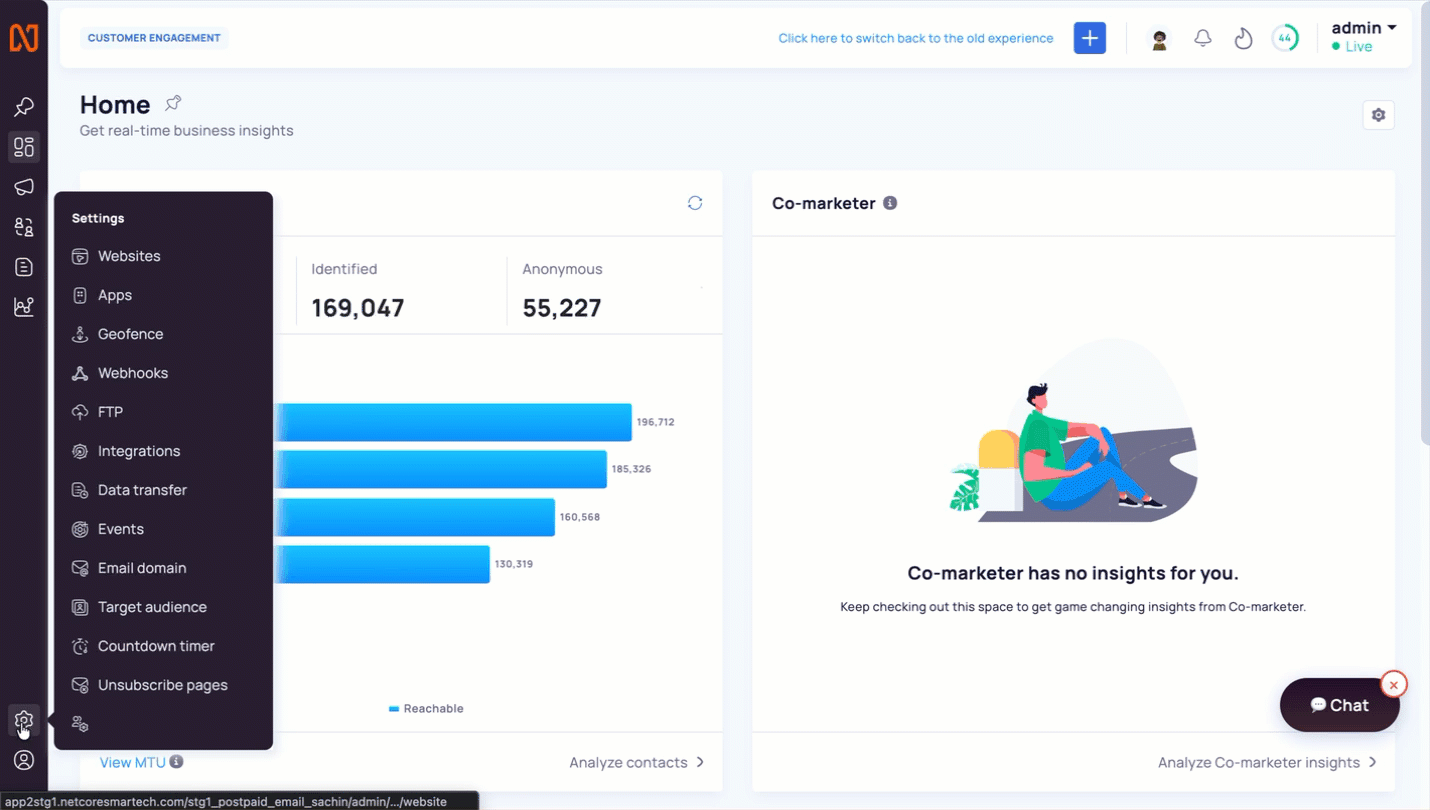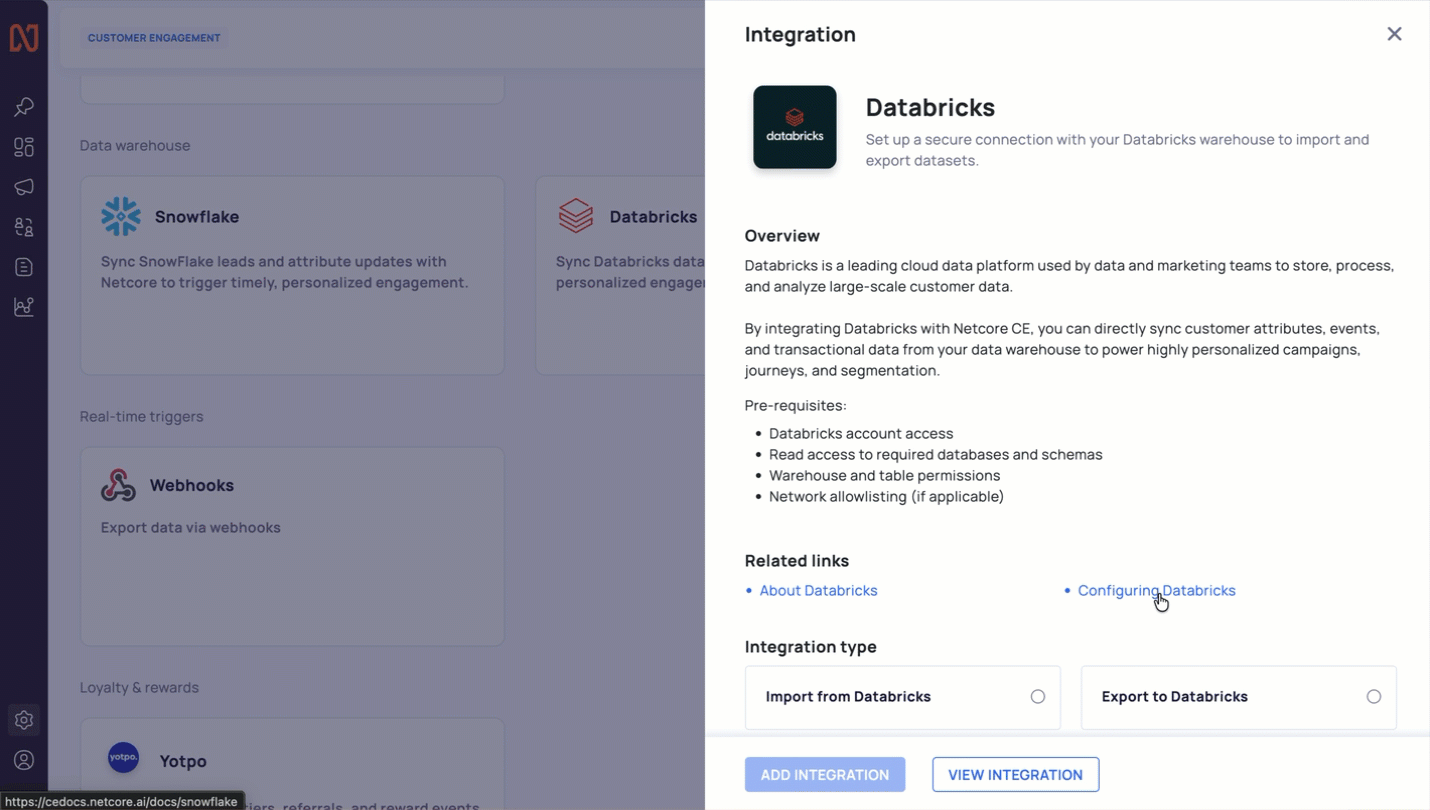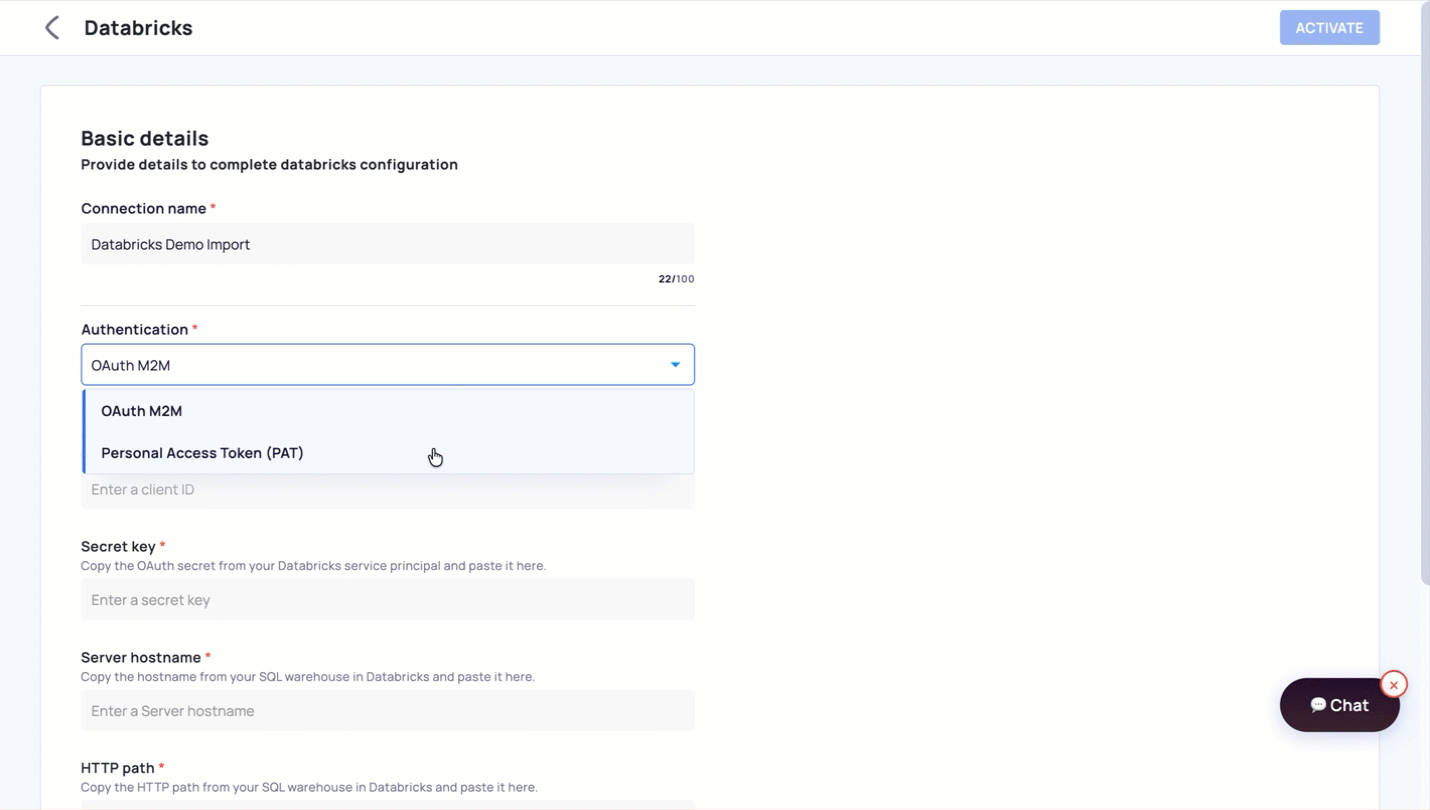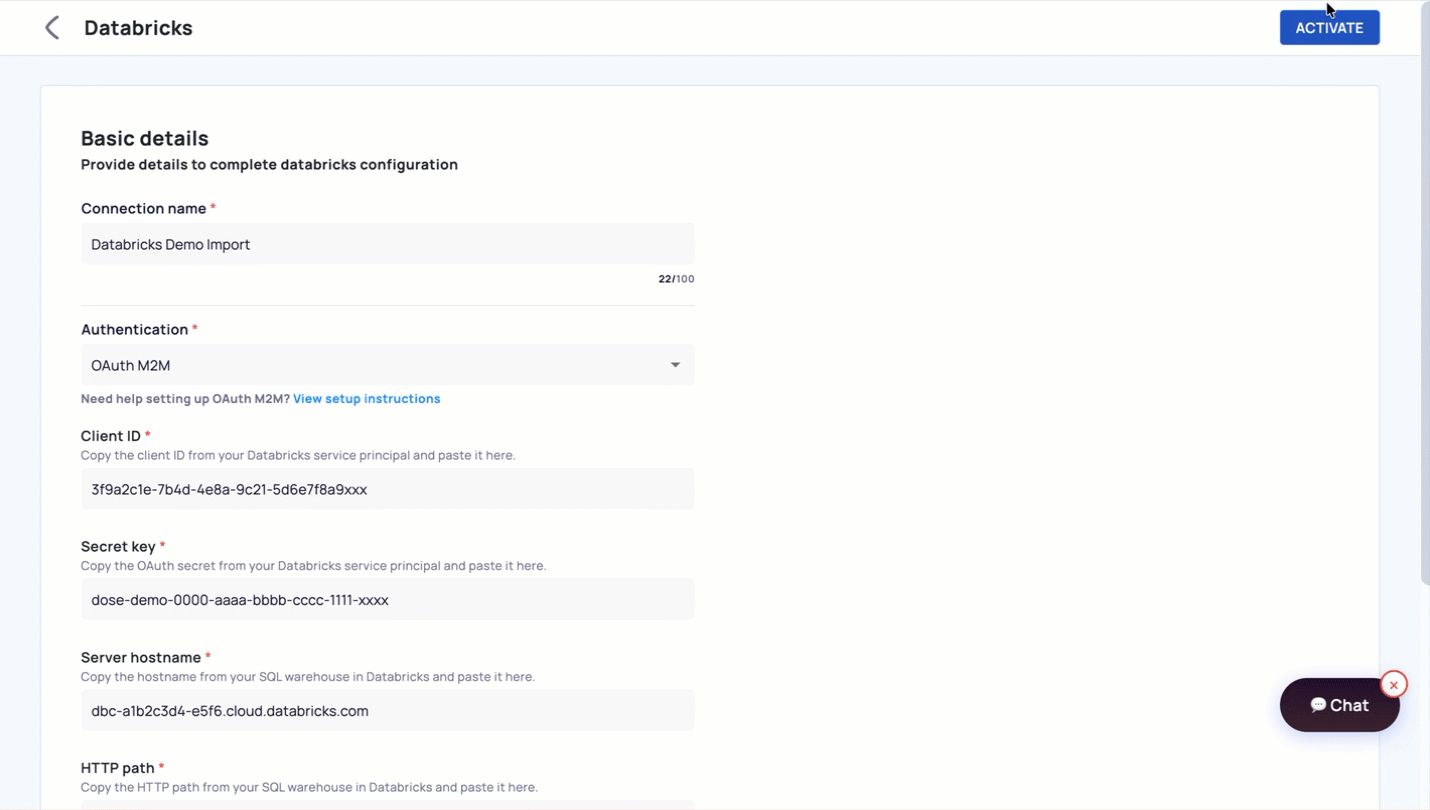
- Log in to the Netcore CE dashboard and navigate to Settings > Data transfer.
- Click the Import tab.
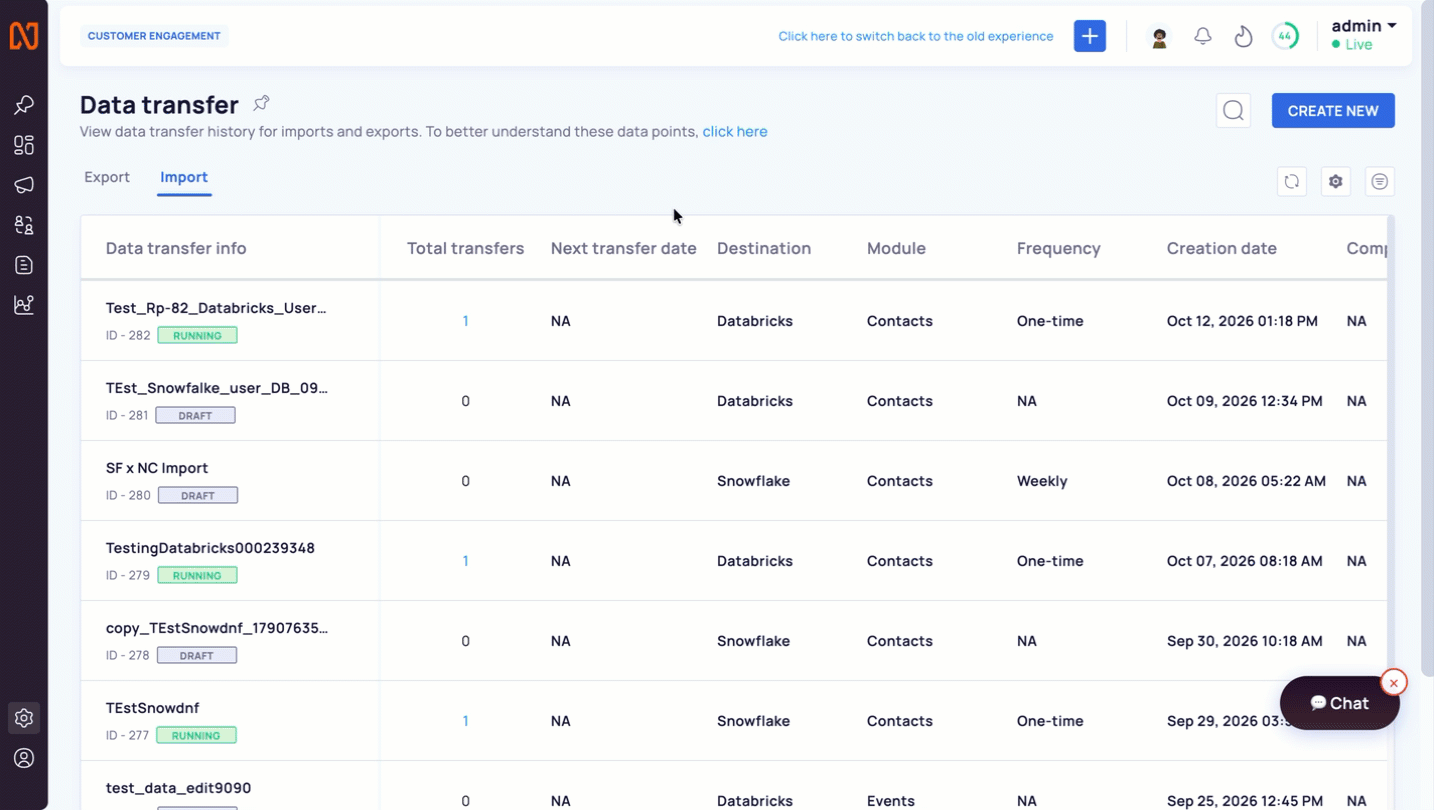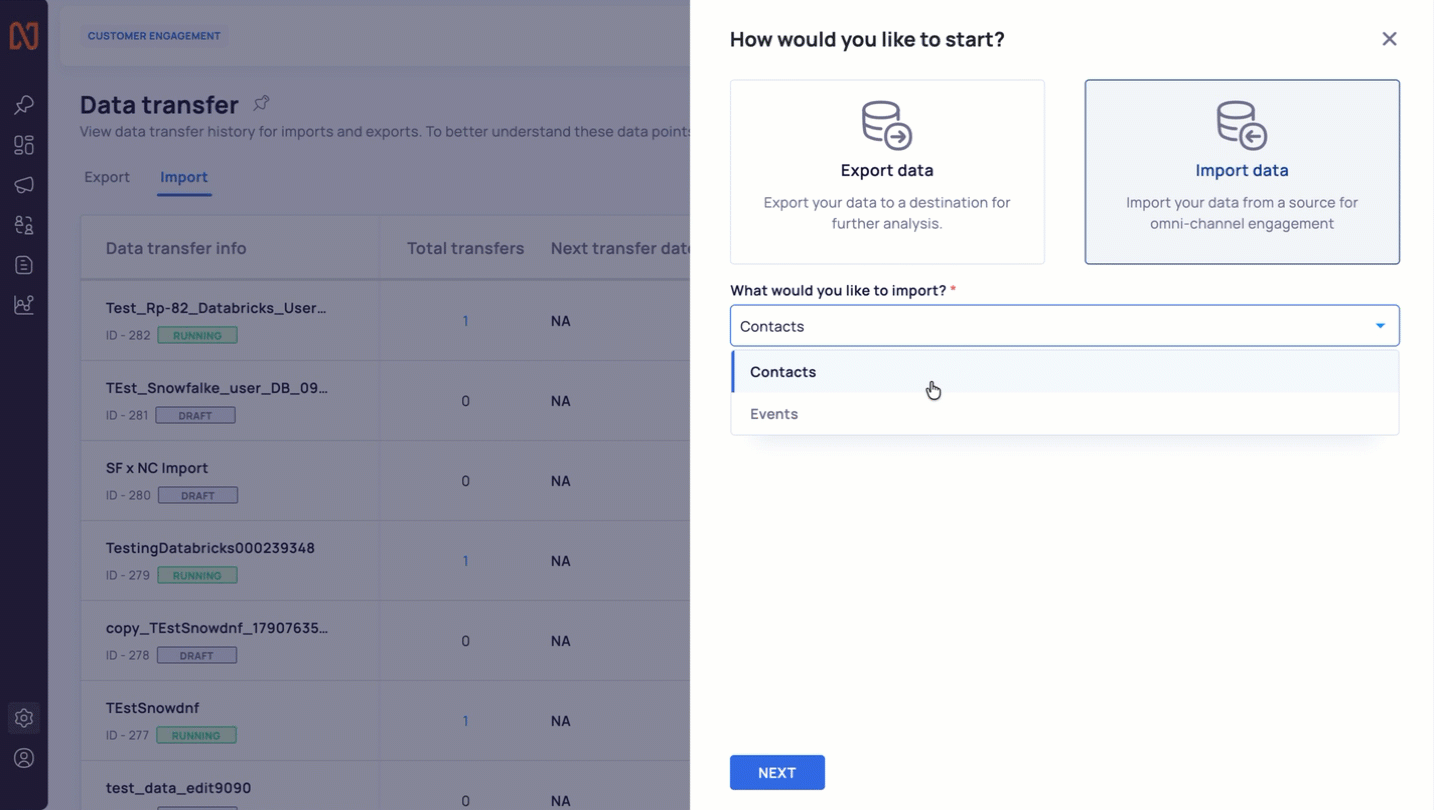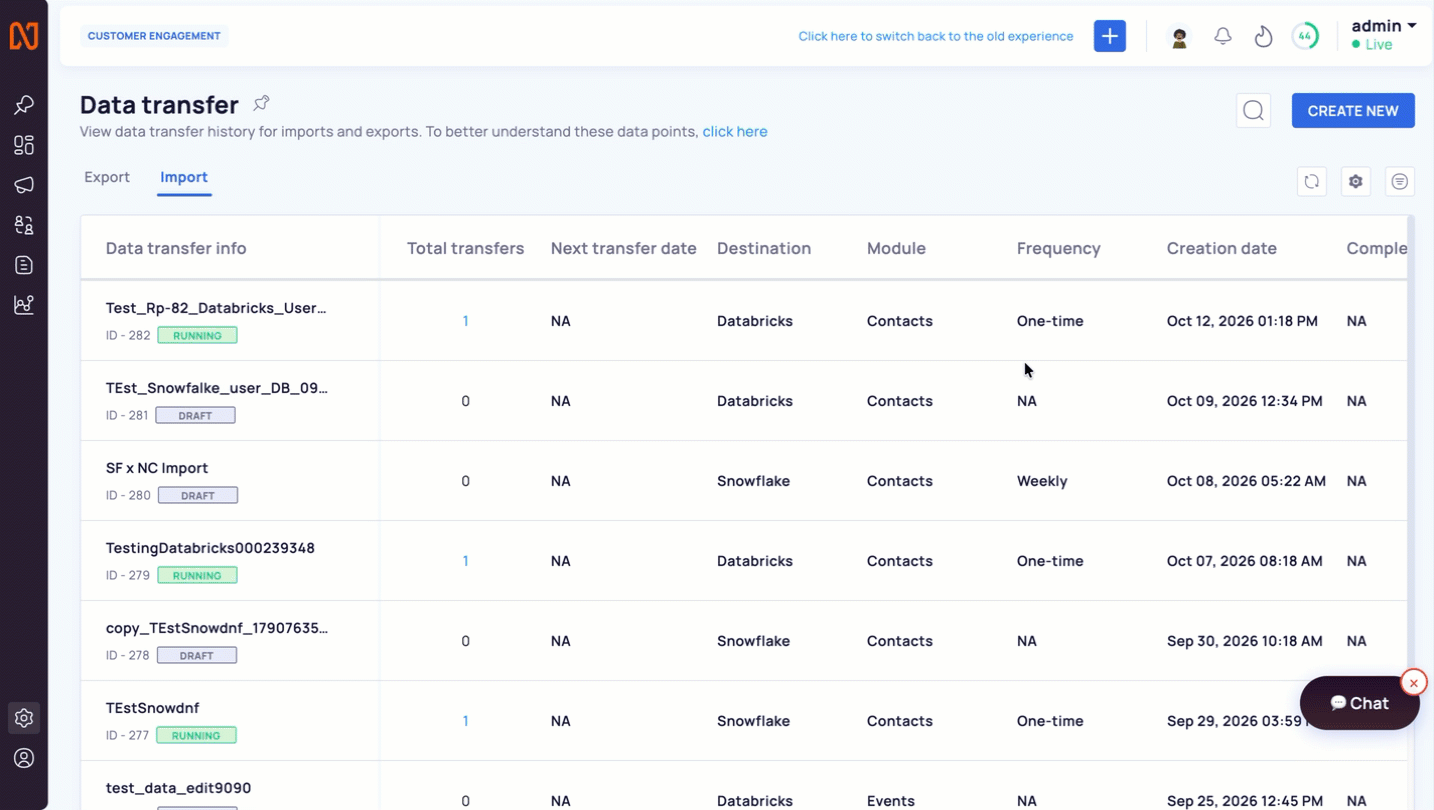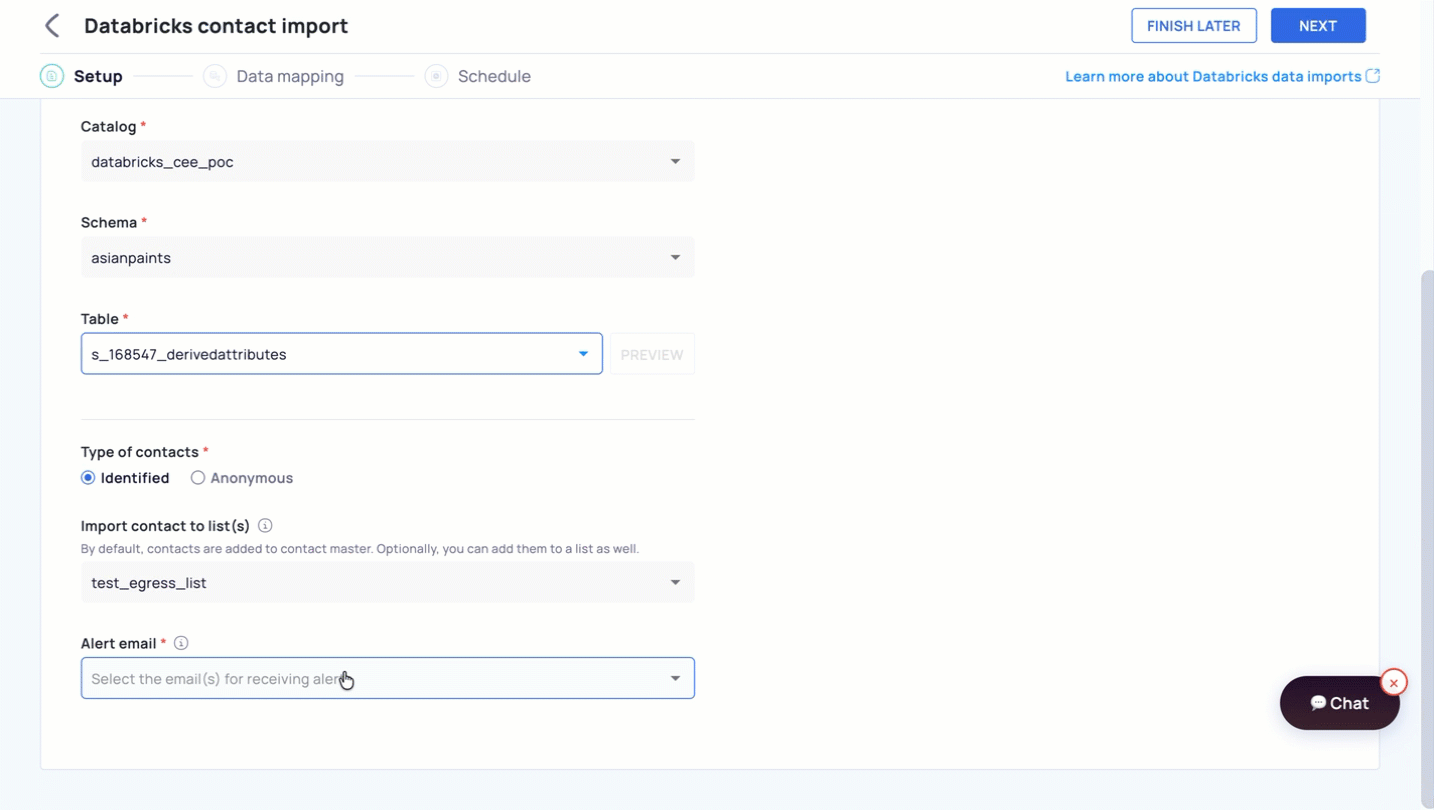
- Click CREATE NEW. A panel titled "How would you like to start?" opens with two options: Export data and Import data.
- Select Import data.
- Under "What would you like to import?", select Contacts. The dropdown also lists Events. This guide covers Contacts.
- Click NEXT. A panel titled "Select a source to import your data" opens. It shows two sources: Snowflake and Databricks.
- Click Databricks.
Create a Databricks Data Import
The Databricks contact import wizard opens. It has three steps: Setup, Data mapping, and Schedule. A "Learn more about Databricks data imports" link appears at the top of the wizard. Click FINISH LATER at any point to save your progress and return to it later.
Step 1: Setup
The Import details section asks for the basic details of your import.
Set up Databricks Contact Import
| Field name | Description |
|---|---|
| Import title | A unique name for this import. Up to 80 characters. |
| Connection | Select an existing Databricks connection that you created under Integrations. |
| Path | Select the path for the import. This field stays disabled until you select a connection. A tooltip reads "Select a connection to choose a path." |
| Catalog | Select the Databricks catalog to import from. |
| Schema | Select the schema within the selected catalog. |
| Table | Select the table or view to import contacts from. |
| Type of contacts | Choose Identified or Anonymous for the imported contacts. Identified is the default. |
| Import contact to list(s) | Optional. By default, Netcore CE adds contacts to the contact master. You can also add them to one or more lists. |
| Alert email | Required. Select the email address or addresses that receive alerts about this import. |
Each field after Connection stays disabled until you complete the field above it.
Preview the Table
After you select a table, click PREVIEW next to the Table field. Netcore CE opens a "Table preview" window that shows a small number of sample records with their column names and values.
Use the preview to confirm that you picked the right table.
Click NEXT to move to Data mapping. Netcore CE saves your setup details at this point.
Step 2: Data Mapping
This step is titled "Data mapping." It asks you to map the columns of your Databricks table to the attributes in Netcore CE.
Identity Mapping
Identity mapping tells Netcore CE which Databricks column to use to match and update contact records.
| Netcore attribute | Requirement |
|---|---|
| EMAIL (Primary key) | Required. Map it to the Databricks column that uniquely identifies each contact. |
| Updated on | Required. Map it to a Databricks column that stores when a record was last updated. |
Click + ADD to add more identity mapping rows if you need them.
When you map Updated on to a column, a date time format dropdown appears next to it. The available formats are:
YYYY-MM-DDYYYY/MM/DDDD/MM/YYYYDD-MM-YYYYDD-MM-YYYY hh:mm:ssYYYY-MM-dd HH:mm:ss.SSS XX
Attributes Mapping
Below Identity mapping, Netcore CE shows a note: "We have detected [N] columns in your table." The count includes only the columns that Identity mapping does not use.
For each detected column, Netcore CE shows:
| Column | Description |
|---|---|
| Column name (Databricks) | The source column name, for example CITY or SIGNUP_TIMESTAMP. |
| Data type | The Databricks data type of the column, for example STRING or TIMESTAMP. |
| Netcore attributes | A searchable dropdown of existing Netcore CE attributes. It lists only attributes with compatible data types. |
| Sample data | An example value from the previewed table for that column. |
| Transformation | For timestamp columns, a Select date time format dropdown that uses the same format list as above. |
| Skip column | A checkbox that excludes the column from this import. |
The Skip all checkbox above the table checks or clears every Skip column checkbox in one action.
Create a New Netcore Attribute
If no existing Netcore CE attribute matches a column, open the Netcore attributes dropdown and select + Create attribute. You create the attribute without leaving this screen.
ValidationYou must map every detected column to a Netcore attribute or mark it as Skip column. If a column stays unresolved, clicking NEXT shows the error "Please map or skip the columns you don't wish to import." Resolve every row before you continue.
Click NEXT to move to Schedule. Netcore CE saves your attribute mapping at this point.
Step 3: Schedule
This step is titled "Import schedule." It asks you to set the schedule for importing your data. The page shows your account timezone and the current date and time, for example "Timezone: Asia/Calcutta."
Select one of two options:
| Option | Behavior |
|---|---|
| One-time | Netcore CE fetches and transfers the complete dataset in the selected table or view. It performs no incremental or ongoing transfer. |
| Recurring | The first run transfers the complete dataset from the selected table or view. All later runs transfer incremental data based on the configured schedule. |
One-time Fields
| Field | Description |
|---|---|
| Scheduled at | The date and time to run the single import. |
Recurring Fields
| Field | Description |
|---|---|
| Start date time | When the recurring schedule begins. |
| End date time | When the recurring schedule ends. |
| Frequency | How often the import repeats, for example Weekly. |
Import Status and Monitoring
The Import tab of Settings > Data transfer lists every import. Each row shows these columns:
| Column | Description |
|---|---|
| Data transfer info | The import title, its ID, and a status badge. |
| Total transfers | The number of transfers that have run. |
| Next transfer date | The date of the next scheduled transfer. Shows NA when none is scheduled. |
| Destination | The data platform linked to the import. |
| Module | The type of data you import, for example Contacts. |
| Frequency | One-time, or the recurring frequency such as Weekly. |
| Creation date | The date you created the import. |
Status badges include Draft, Running, and Stopped.
Error Handling
| Error message | Cause |
|---|---|
| "Please select a date-time format for 'Updated on'." | The Updated on identity mapping points to a column with no valid date time format selected. |
| "Please map or skip the columns you don't wish to import." | One or more detected columns in Attributes mapping are neither mapped to a Netcore attribute nor marked Skip column. |
Important Notes and Limitations
- This guide covers the Contacts import type. The "What would you like to import?" dropdown also lists Events.
- A Databricks connection must exist and be active before you create an import. See Databricks.
- The connection must have read access to the catalog, schema, and table you select. Netcore CE cannot list or import data that the connection cannot read.
- EMAIL (Primary key) and Updated on are mandatory identity mappings. You cannot continue without them.
- Click FINISH LATER to save your progress and resume the import later.
FAQs
How do I import contacts from Databricks into Netcore CE?
Go to Settings > Data transfer > Import and click CREATE NEW. Select Import data, choose Contacts, and select Databricks as the source. Then complete the Setup, Data mapping, and Schedule steps.
What do I need before I create a Databricks import?
You need an active Databricks connection of type Import, read access to the source catalog, schema, and table, and at least one alert email address.
Which fields does Netcore CE require for identity mapping?
Netcore CE requires EMAIL (Primary key) and Updated on. Map Updated on to a column that stores the last update time of each record, and select a date time format for it.
What is the difference between a One-time and a Recurring import?
A One-time import transfers the complete dataset once at the scheduled date and time. A Recurring import transfers the complete dataset on the first run, then transfers only incremental data on later runs.
Can I skip columns I do not need?
Yes. Select the Skip column checkbox for each column you want to exclude. Use Skip all to select every column at once. You must map or skip every detected column.
Can I create a new attribute during mapping?
Yes. Open the Netcore attributes dropdown for a column and select + Create attribute.
Can I save my progress and finish later?
Yes. Click FINISH LATER at any point in the wizard. Netcore CE saves your progress so you can resume later.
Which contacts does Netcore CE add to lists?
Netcore CE adds all imported contacts to the contact master. If you select one or more lists in Import contact to list(s), it also adds the contacts to those lists.
Updated 1 day ago